
Consider the following definition of a lexical token id for an identifier in a programming language, using extended regular expressions:
letter \(\to\) [A-Za-z]
digit \(\to\) [0-9]
id \(\to\) letter (letter | digit)\(^{*}\)
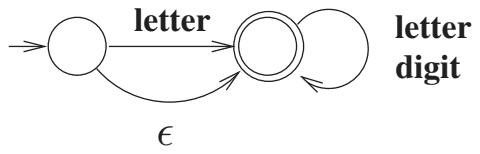
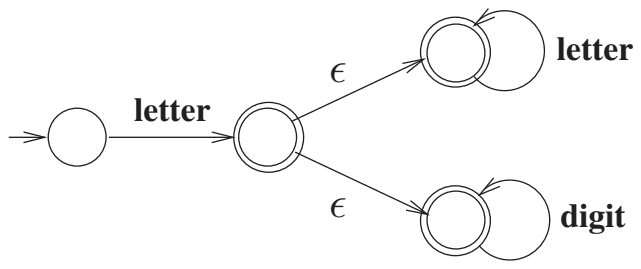
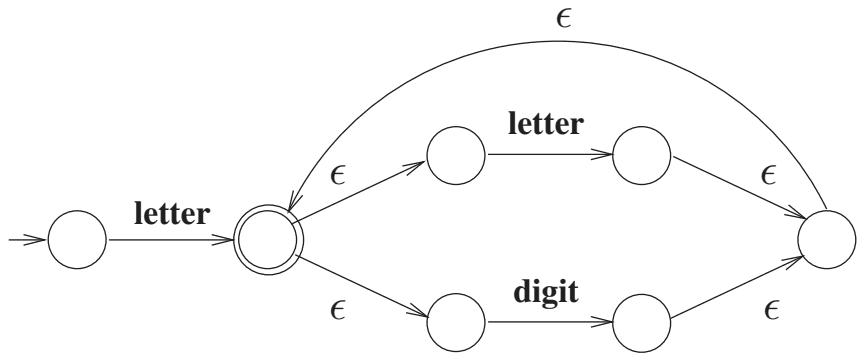
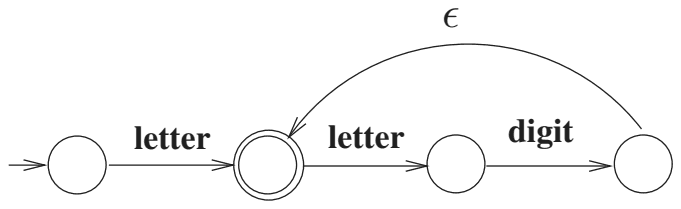
Which one of the following Non-deterministic Finite-state Automata with \(\epsilon\)-transitions accepts the set of valid identifiers? (A double-circle denotes a final state)
GATE CS - 2023,
Answer: C
The correct automaton is (C).
In (C), a letter takes the start state to the final state. From there, \(\epsilon\)-moves lead into two branches, one reading a single letter and one reading a single digit, and both rejoin a state with an \(\epsilon\)-move back to the final state. So after the first letter the machine can read any number of letters and digits in any order: exactly letter (letter | digit)*.
(A) has an \(\epsilon\)-move from the start state straight to the final state, so it also accepts the empty string and strings starting with a digit. (B) commits to one branch after the first letter, so it accepts a1 and ab but not a1b, which mixes letters and digits. (D) loops only on the pair 'letter digit', so it rejects ab.
Please log in or register to report this question.